Image
Run image generation, editing and upscaling in interactive or batch workflows.
Hedra’s inference engine for image, video and world models. We tune kernels, numerical precision and scheduling for supported NVIDIA and AMD GPUs.
Bring supported weights you own, license or build with Hedra.
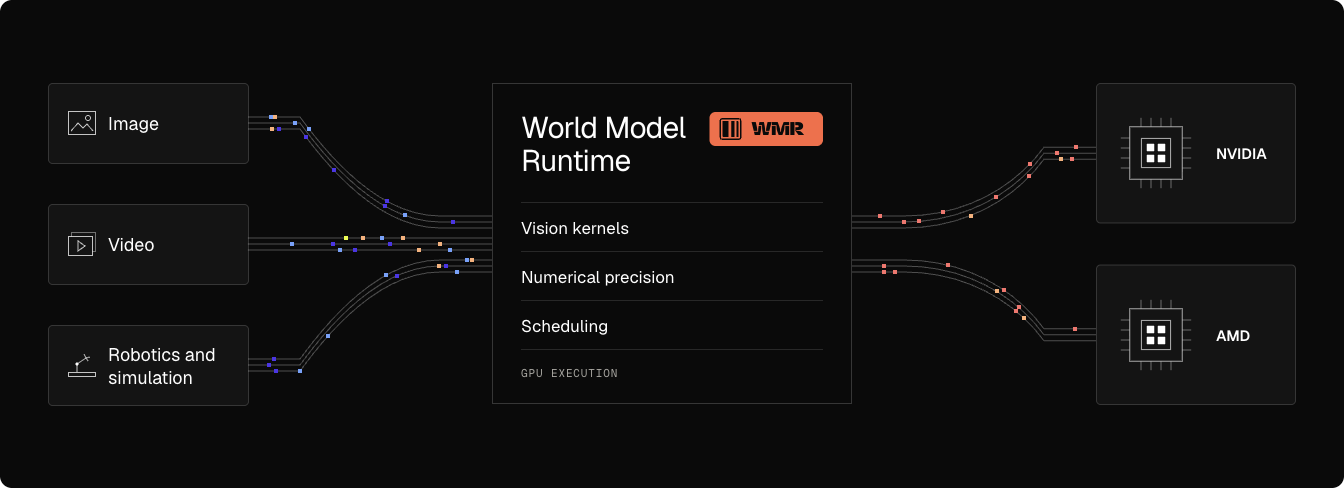
Supported model workloads
Image
Video
Robotics + simulation
Shared engine

World Model Runtime
Vision kernels
Numerical precision
Scheduling
Execution
GPU execution
NVIDIA
AMD
Support agreed per workload
Run image generation, editing and upscaling in interactive or batch workflows.
Generate video from text or images, including for streaming workloads.
Run vision-language-action policies and action-conditioned world models.
Built from our experience training and serving Hedra’s own models.

We fuse operations for spatial-temporal attention, VAE encoding and decoding, and diffusion.
We test how quantization affects image and video output quality.

We batch requests and cache reusable computation around fixed-step generation.

We confirm model, GPU and precision support for your workload.
Krea 3 GEMM kernel time on AMD Instinct MI355X.
PyTorch BF16 baseline
4.34 ms
Hedra custom MXFP6 kernel
1.54 ms
Profiler timings cover one GPU’s share of the MLP’s matrix multiplications. Both measurements use the same matrix shapes.